

Noema 1.5 4B is our third open-weight release: one 4B model, post-trained from Qwen3.5-4B, in two reasoning styles. Deep thinks longer and is the more accurate of the two. Fast answers in a fraction of the tokens and almost never gets stuck. Both are released as open weights, and both run in the Noema app.
Under Qwen's own recommended preset, both styles score about 15 to 16 points higher than Qwen3.5-4B on GPQA Diamond within a 32,768-token limit. On a stress test of 1,000 hard prompts, Fast falls into repetition loops on 1.1% of them, against 65.0% for its base model.
Two styles, one size
Both styles have the same size and run on the same devices. What separates them is how long they think. The rule of thumb: Fast for everyday questions and phones, Deep for hard problems when you can wait.
| Deep | Fast | |
|---|---|---|
| Emphasis | Accuracy first | Speed first |
| Best for | Hard mathematics and competitive programming, when an answer is worth waiting for. Suits a Mac. | Everyday questions, science and writing, on phones or with tight output budgets. |
| Typical answer | 14K tokens on GPQA Diamond, 23K on AIME 2026 | 9K tokens on GPQA Diamond, 16K on AIME 2026 |
| Output limit | 81,920 tokens for contest math and code, 32,768 otherwise | 32,768 tokens |
| Trade-off | Under Qwen's default preset it trails Qwen3.5-4B on AIME and HMMT. About 14% of hard stress-test prompts run past 32K tokens. | Competition math: about 16 points behind Qwen3.5-4B on AIME and HMMT under Qwen's preset, and 8.3 behind on AIME at temperature 0.6. |
Evaluation
Every comparison is paired against stock Qwen3.5-4B on identical items, in one harness, with the same prompts, answer extraction, graders, sampling settings and output limits. Each difference comes with a 95% interval from 10,000 bootstrap resamples, and we call it a gain or a loss only when the interval excludes zero. The benchmark panel and the loop stress test were held out from training and checkpoint selection.
Under Qwen's preset
| Benchmark | Qwen3.5-4B | Deep | Fast |
|---|---|---|---|
| GPQA Diamond | 59.1 | 74.7 (+15.6) | 75.4 (+16.3) |
| arxivmath 0826 | 1.4 | 4.3 (+2.9) | 4.3 (+2.9) |
| IFEval | 90.8 | 92.4 (+1.7) | 92.6 (+1.8) |
| MMLU-Pro | 79.1 | 79.6 (+0.5) | 78.6 (−0.5) |
| LiveCodeBench v6 | 57.1 | 53.6 (−3.6) | 51.6 (−5.6) |
| HMMT Feb 2026 | 64.0 | 60.2 (−3.8) | 47.7 (−16.3) |
| AIME 2026 | 85.4 | 80.4 (−5.0) | 69.2 (−16.2) |
The GPQA Diamond gain is the clearest, and part of it is finishing: at 32,768 tokens, a third of Qwen3.5-4B's answers are still being written and count as wrong. Deep answers in about 14.1K tokens and Fast in 9.4K, against 22.8K for the base. Given 81,920 tokens, Qwen3.5-4B reaches 75.9 at 28.9K tokens per answer, level with both styles within noise.
Under this preset Qwen3.5-4B scores higher on competition math (AIME and HMMT) than both styles, and higher than Fast on LiveCodeBench. Across all seven benchmarks the mean difference is +1.2 points for Deep and −2.5 for Fast.
At temperature 0.6
At temperature 0.6, our recommended setting and Qwen's suggestion for precise coding, Deep is at or above Qwen3.5-4B on all seven thinking benchmarks with 1.2 to 3.1 times fewer tokens; the mean difference is +12.0 points for Deep and +9.2 for Fast. Much of that margin comes from answers Qwen3.5-4B leaves unfinished at the output limit under this setting, which are scored as wrong for every model. Fast trails Qwen3.5-4B on AIME 2026 by 8.3 points.
Accuracy per token
Averaged over AIME 2026, HMMT Feb 2026, LiveCodeBench v6 and GPQA Diamond under Qwen's preset, Deep reaches its base model's mean accuracy (67.2 against 66.4) with about 40% fewer tokens per answer (22.1K against 37.4K). Fast gives up about five points of that mean (61.0) for answers less than half as long (14.4K).
Fewer loops
Small reasoning models often get stuck: they repeat a passage, or keep reasoning until they run out of room and never answer. We measure this on a stress test of 1,000 held-out prompts weighted toward hard problems (400 hard math, 200 science, 200 code, 100 open-ended and 100 multi-turn), so its rates are not everyday rates.
| Setting | Qwen3.5-4B | Deep | Fast |
|---|---|---|---|
| Greedy decoding | 65.0% | 13.9% | 1.1% |
| Sampled, temperature 1.0 | 41.0% | 12.3% | 0.6% |
| Qwen's preset | 29.6% | 8.8% | 0.1% |
| Q4_K_M on llama.cpp | 46.8% | 13.6% | 0.6% |
| Long conversations with a loop, of 100 | 51 | 0 | 0 |
Deep reasons longer: on 14% of the stress test it is still working at 32,768 tokens. Given the 81,920 tokens Qwen recommends for hard problems, every one of those answers finishes, while Qwen3.5-4B is still repeating itself on an estimated 58%. On the same 1,000 prompts, greedy accuracy rises from 16.5% for Qwen3.5-4B to 47.2% for Deep and 49.2% for Fast.
Where it falls short
- Under Qwen's default preset, both styles trail Qwen3.5-4B on AIME 2026 and HMMT Feb 2026, and Fast also on LiveCodeBench v6.
- Fast trails on competition math in every setting: about 16 points on AIME and HMMT under Qwen's preset, 8.3 on AIME at temperature 0.6.
- Without thinking, the three models are close; Fast is lower on LiveCodeBench v6 (−4.9, significant).
- Loop rates come from a stress test weighted toward hard prompts; they are not everyday rates.
- One training run per style, evaluated in English, text only, with outputs up to 81,920 tokens.
How to run it
In the Noema app, both styles appear first in Explore. Fast suits iPhone; Deep suits Mac. Each is a separate download of about 2.7 GB at Q4_K_M.
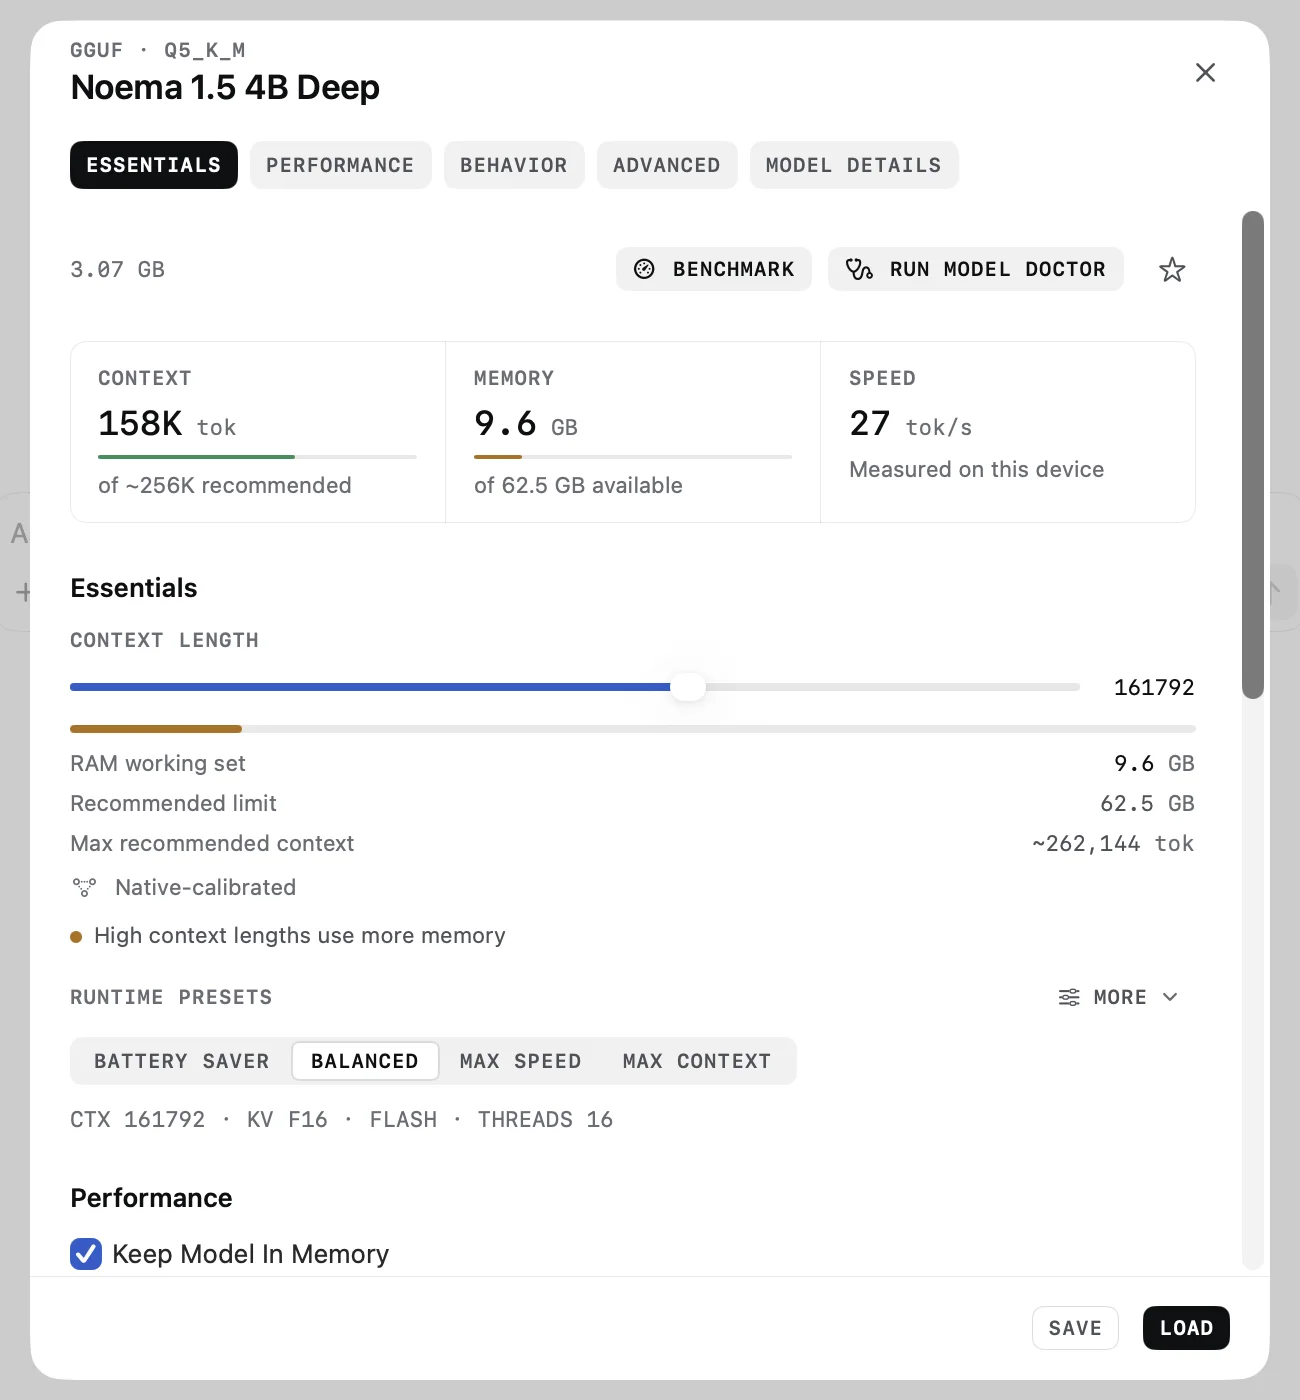
Outside Noema, the weights are on Hugging Face as Transformers (SafeTensors), GGUF (BF16 to Q4_K_M) and MLX (BF16 to 4-bit) builds. Use thinking mode at temperature 0.6, top-p 0.95 and top-k 20. These commands come from the model cards:
llama-server -hf NoemaAI-labs/Noema-1.5-4B-Fast-GGUF:Q4_K_M --jinja -c 40960 \
  --temp 0.6 --top-p 0.95 --top-k 20 --min-p 0
Availability
Noema 1.5 4B Deep and Fast are available now on Hugging Face and in the Noema app. They are open weights, not open source: the weights are publicly downloadable, but no open-source license is granted. The model card has the details, and ships the Apache 2.0 license of the Qwen3.5-4B base model as LICENSE-Qwen3.5.
Every benchmark, token count and confidence interval, including the settings where Noema 1.5 4B loses, is on the model page.